Pelican benchmark · updated 2026-10-06
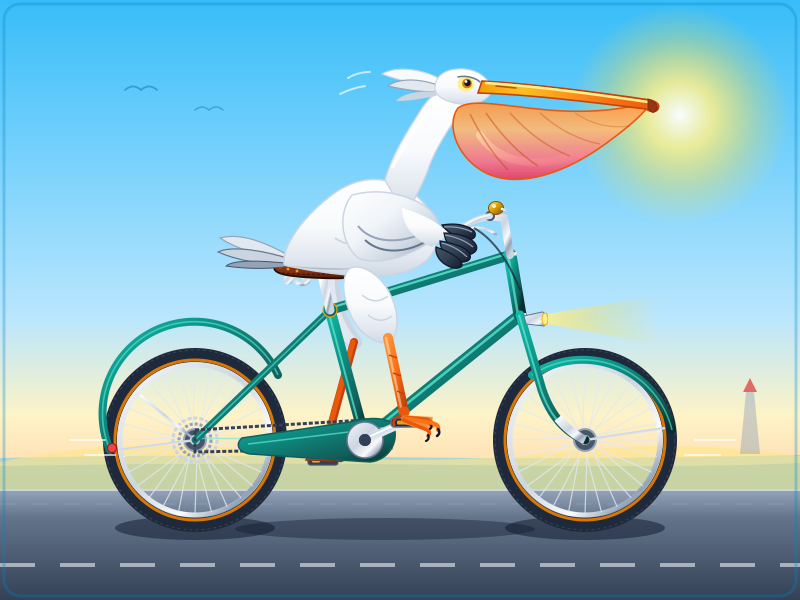
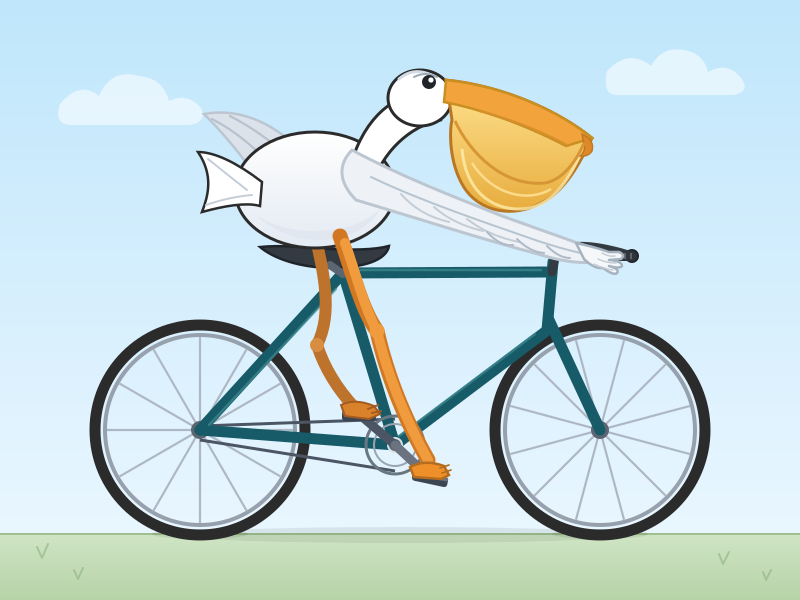
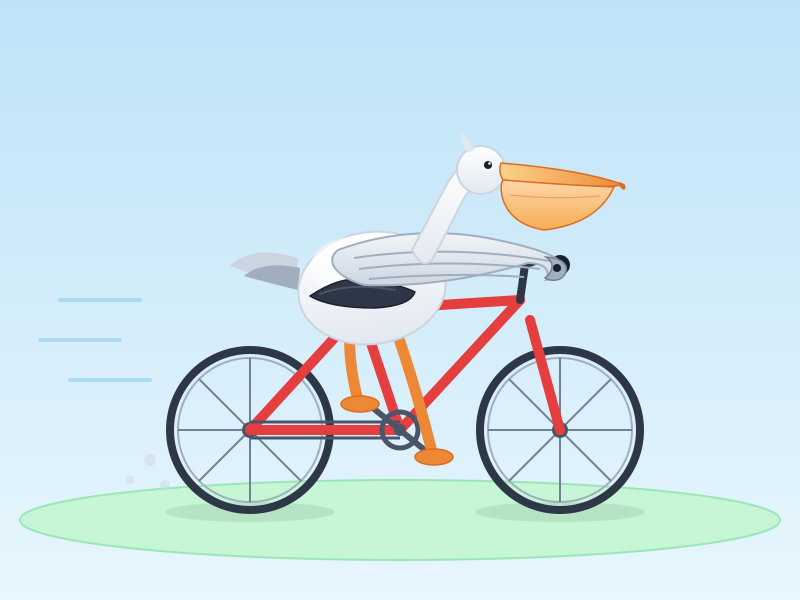
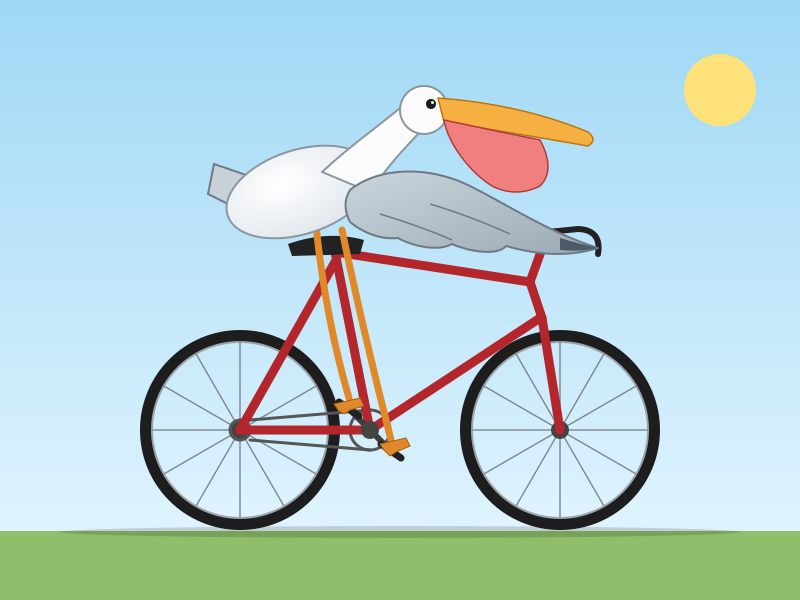
Can a coding agent draw a pelican riding a bicycle?
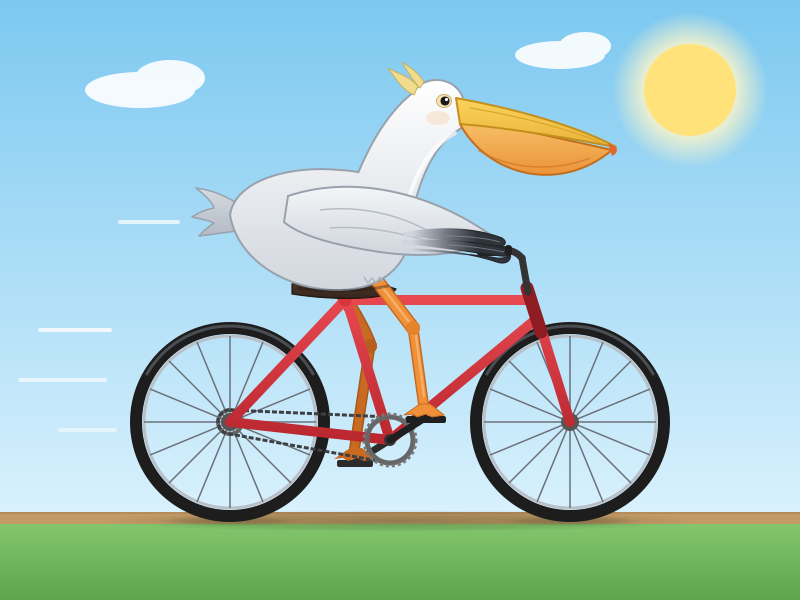
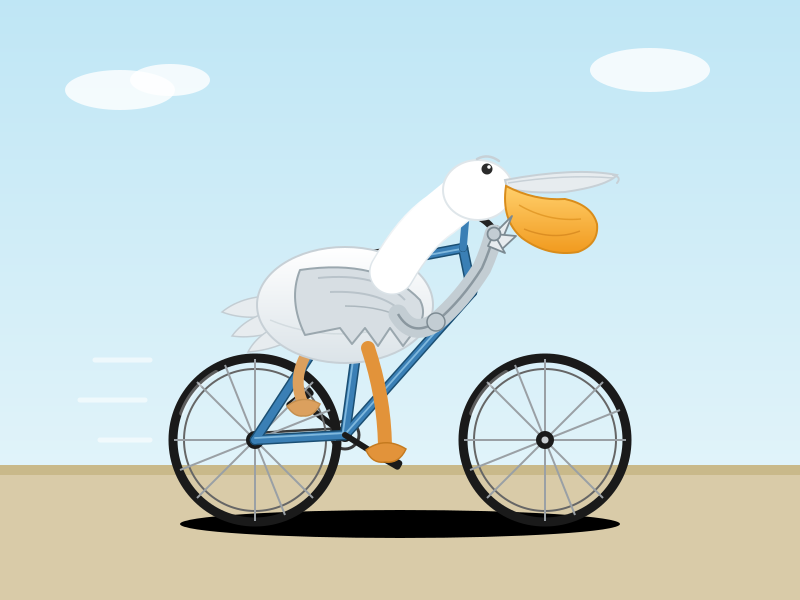
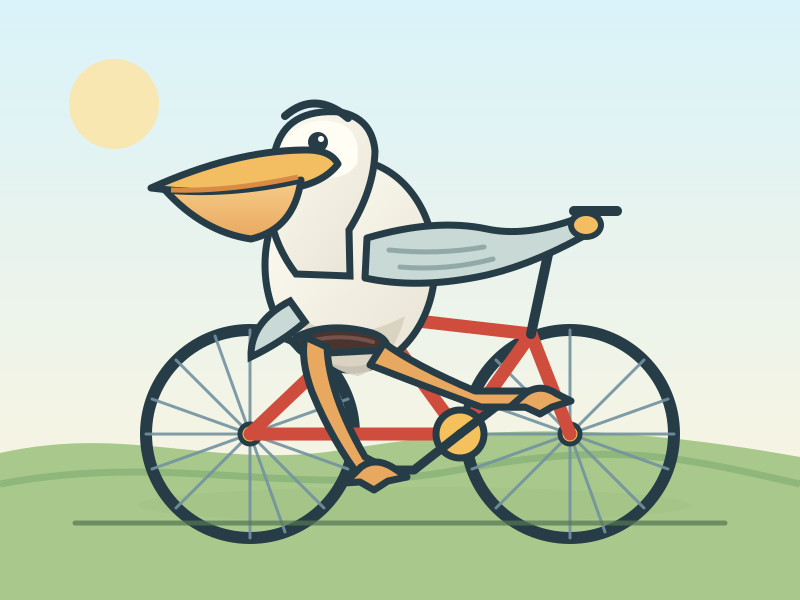
16 agent and model pairs draw it in SVG and improve it round after round; an external judge scores all 108 drawings.
The v2 lineup, judged from outside.
Where the v2 birds are strong and weak
External judge score per rubric axis (0–10), best round per agent. Hover an axis for values.
Show as table
| Agent | Pelican | Bicycle | Composition | Polish | Total |
|---|---|---|---|---|---|
| claude-code · Opus 5.5 | 8.5 | 8 | 8.3 | 8 | 32.8 |
| claude-code · Sonnet 5 | 7.5 | 5 | 6.5 | 6.3 | 25.3 |
| opencode · GPT-5.6 Terra | 7.2 | 6.5 | 7.2 | 7.2 | 28 |
| opencode · Gemini 3.8 Flash | 8.7 | 7.7 | 8 | 8.5 | 32.8 |
| hermes · Jev Router | 8 | 7.7 | 8.3 | 7.7 | 31.7 |
| opencode · Mistral Large 4 | 7.7 | 6.3 | 7.3 | 7.5 | 28.8 |
| claude-code · Haiku 5.5 | 7 | 6.8 | 7.3 | 6.8 | 28 |
Agents grade themselves generously
Same drawing, two scores out of 40: the agent's self-score and an external judge (Claude Opus 5.5, temperature 0, three samples averaged). Click a row to open that agent's runs.
Show as table
| Agent | Cohort | Judge | Self-score | Inflation |
|---|---|---|---|---|
| opencode · Gemini 3.8 Flash | v2 | 32.8 | 38.5 | +5.7 |
| claude-code · Opus 5.5 | v2 | 32.8 | 36 | +3.2 |
| hermes · Jev Router | v2 | 31.7 | 37 | +5.3 |
| gemini-cli · Gemini 3.5 Flash | v1 | 29.8 | 40 | +10.2 |
| opencode · Gemini 3.5 Flash | v1 | 29.3 | 40 | +10.7 |
| hermes · Fusion router | v1 | 28.8 | 34 | +5.2 |
| opencode · Mistral Large 4 | v2 | 28.8 | 36 | +7.2 |
| claude-code · Opus 4.7 | v1 | 28.7 | 36 | +7.3 |
| opencode · Fusion router | v1 | 28.3 | 36 | +7.7 |
| hermes · Gemini 3.5 Flash | v1 | 28.2 | 39.5 | +11.3 |
| opencode · GPT-5.6 Terra | v2 | 28 | 38 | +10 |
| claude-code · Haiku 5.5 | v2 | 28 | 29 | +1 |
| hermes · GLM 5.1 | v1 | 27.3 | 36.5 | +9.2 |
| claude-code · Sonnet 4.6 | v1 | 26.2 | 37 | +10.8 |
| claude-code · Sonnet 5 | v2 | 25.3 | 36 | +10.7 |
| hermes · Sonnet 4.6 | v1 | 24 | 36 | +12 |
Questions answered from the runs.
Which agent and model draw the best pelican on a bicycle?
opencode · Gemini 3.8 Flash and claude-code · Opus 5.5 tie for the best pelican at 32.8/40 from the external judge, ahead of hermes · Jev Router at 31.7. Current models beat last spring's: the v2 cohort averages 29.6 against 27.9 for v1. The gaps are a few points on one judge with one lineage per setup, so rank the top three as a group and re-run before choosing between them.
Are the evals doing anything?Do coding agents grade their own drawings accurately?
No. Agents score their own drawings a median 8.4 points (of 40) above the external judge, and across 108 drawings the two scores correlate at only 0.25. As a gate, the self-score passes 107 of 108 runs at 28/40 while the judge passes 58, so the v2 runbook's self-score check cannot fail a weak drawing. Score with an external judge instead.
Did the change help?Does hill-climbing on self-scores actually improve the drawing?
Mostly not. Across 15 lineages with three or more rounds, self-scores rose 2.2 points from round 1 to their best, but the judge scored the last round 0.8 points lower than the first on average, and 9 of 15 ended below where they started. The climb steers by the self-score, which barely tracks the judge; steer it by the judge and stop when the judge stops improving.
Data: results.json · judge-raw.json. Inspired by Simon Willison's pelican-riding-a-bicycle benchmark.
Author, run, then investigate.
Tell Jetty the job to be done
The runbook, a four-axis rubric, code checks and an external vision judge. Now in Jetty's evals-v2 shape.
02 · RunsEvery run, with its inputs, outputs, cost and evaluation
Every hill-climb round is a Jetty trajectory, with its drawing, self-score, judge score, verdict and cost.
03 · InvestigationsQuestions answered from the runs
Which setup draws best, whether the agents grade themselves honestly, and whether the climb helps.
FAQ
Which AI agent draws the best pelican riding a bicycle?
Scored by one external vision judge (Claude Opus 5.5, temperature 0, three samples averaged, four axes of 0–10), the best drawings came from: opencode · Gemini 3.8 Flash 32.8/40; claude-code · Opus 5.5 32.8/40; hermes · Jev Router 31.7/40. Scores are for the round each agent picked as its best after hill-climbing on Jetty.
Do coding agents grade their own drawings accurately?
No. Across 16 agent and model pairs, the median agent scored its own best drawing 8.4 points (out of 40) higher than the external judge did, and across 108 drawings the correlation between self-score and judge score is 0.25.
Does hill-climbing improve the drawing?
Not by the judge's measure. Across 15 lineages with three or more rounds, self-scores rose 2.2 points on average from round 1 to their best, while the judge's score for the last round was 0.8 points lower than for round 1.
How is the pelican benchmark scored?
Each drawing is a hand-written SVG (800x600, under 50 KB, no embedded images). It is scored on four axes: Pelican, Bicycle, Composition and Polish, 0 to 10 each, for a maximum of 40, both by the agent itself and by an external vision judge.
Can I run the pelican benchmark myself?
Yes. It is a Jetty runbook (pelican-bicycle-svg), now in the evals-v2 shape with code checks, a checklist and a validation report. Author your own runbook in your Jetty collection (see jetty.io/docs/ai-workloads/runbooks), add an OPENROUTER_API_KEY, and run it with any supported agent and model. How this one works: evaljetty.com/pelicans/author.html#runbook.